4:00 pm ET
“Dealing with AI Security ‘findings’ — a practical guide to not throwing your laptop in a lake”
with Holden KarauFor anyone maintaining an open source project, it's likely only a matter of time until you start to receive largely AI driven security reports in addition to the AI driven pull requests. Even those who don't maintain open source projects, seeing what's happening behind the scenes in OSS projects will help you understand why your favourite OSS project might seem to have a huge number of "[MINOR][FIX]" commits instead of cool new features right this second.
Historically, we've handled security reports with more caution than pull requests since rejecting a correct security report can have large negative impacts, and the effort required to find a security problem in a project was high.
Now, for better or worse, the effort being high part has changed; so how do we change our responses? This talk will use Holden Karau's personal experience with the Spark 3.5.9/4.0.4/and 4.1.3 releases to look at how to handle a deluge of (non-opt-in) security reports from external developers; as well as how to handle opt-in security reports from select AI labs (if you are granted such a "privilege.") We'll also look at why these AI security reports leave a lot to be desired and hopefully give you some steps to avoid just giving up and throwing your laptop in the nearest large body of water.
Meet Holden Karau
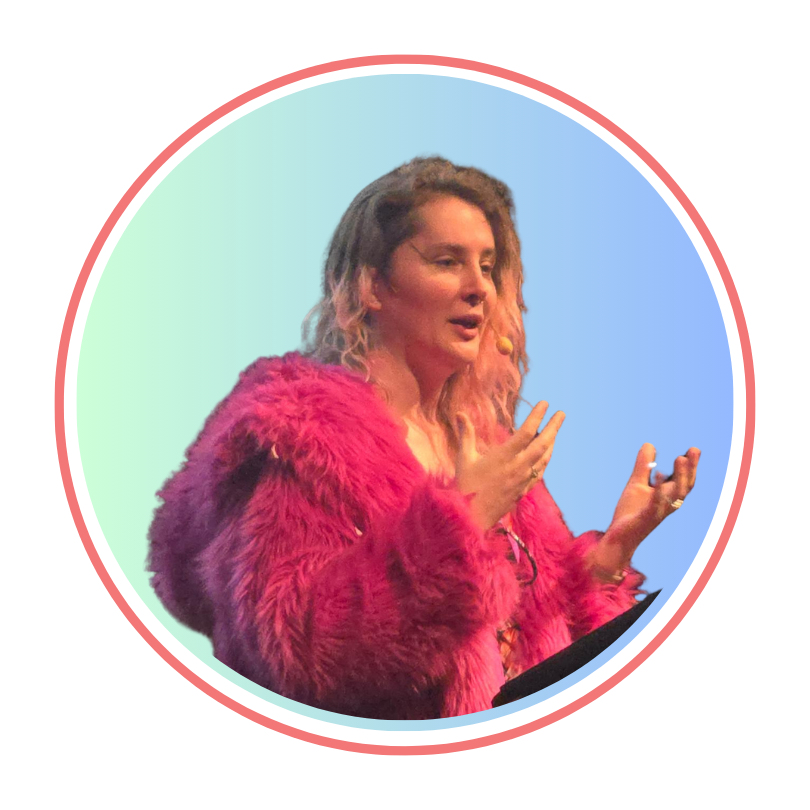
Holden is a transgender Canadian open source developer at Snowflake with a focus on Apache Spark. She is the co-author of Learning Spark, High Performance Spark, and a few others that she would love you to buy. She is a committer and PMC on Apache Spark. She was tricked into the world of big data while trying to improve search and recommendation systems and has long since forgotten her original goal. In her spare time she is building a tool to fight health insurance denials https://www.fighthealthinsurance.com, spinning sticks, playing with fire, and riding motorcycles.
Recent Events
#51 Join the Forge: Contributing Your First Package to conda-forge
Travis Hathaway — September 30, 2026
Recording Coming Soon!
conda-forge is a thriving packaging ecosystem with well over 30,000 packages and hundreds of active package maintainers. It's these package maintainers that are the lifeblood of this ecosystem. In this talk, I cover how you can contribute your own packages, why this is beneficial and even more ways to get involved with our community. During the talk, I also briefly cover the history of conda-forge and peak behind the currents to show how its maintainers ensure stability for its users.
Coming Soon#50 Nebi: Environment management for teams
Dharhas Pothina — August 26, 2026
Reproducibility of your software environments is often treated like an afterthought. By the time you’re thinking about it, it’s already too late.
We encountered this time again with clients and built a solution in the form of a conda-store which introduced versioning, role-based-accessed control, and most importantly: reproducibility, to conda environments on platforms like JupyterHub.
While effective, the project required heavy infrastructure, had slow environment solves, and was tied to a server-first world of global conda environments. Meanwhile, tools like Pixi and uv have transformed Python packaging with lockfiles and project-oriented workflows, improving reproducibility, but only for individual developers.
In this presentation, we introduce Nebi, a new open-source tool that brings multi-user environment management to the modern Python packaging era, supporting both project-oriented and shared global environments with versioning, role-based access control, and sharing via publishing through OCI registries as well as standalone servers.
Watch on Youtube#49 Bridging the conda and PyPI Ecosystems
Dan Yeaw — July 29, 2026

If you've ever wondered why pip install numpy and conda install numpy
aren't the same thing, you've bumped into one of Python packaging's oldest
fault lines. Conda and PyPI evolved to solve different problems: one for
compiled scientific libraries, one for pure-Python packages. The gap between
them has caused headaches ever since. In this talk, we'll explore why the
split happened, what's fundamentally different under the hood, and how the
two ecosystems are finally starting to come together.
About Us
At Don’t Use This Code, we want to create a unique opportunity to see Python succeed and thrive within the National Labs! We propose creating a new resource for scientists, researchers, and technical staff to support their use of Python and to build a strong, lasting community for Python users within the Department of Energy National Labs. Disclaimer: The Python Exchange is an independent group of Python enthusiasts who wish to see the use of Python and open-source computing thrive within the National Lab system. This group is not sponsored by or affiliated with the Department of Energy.